

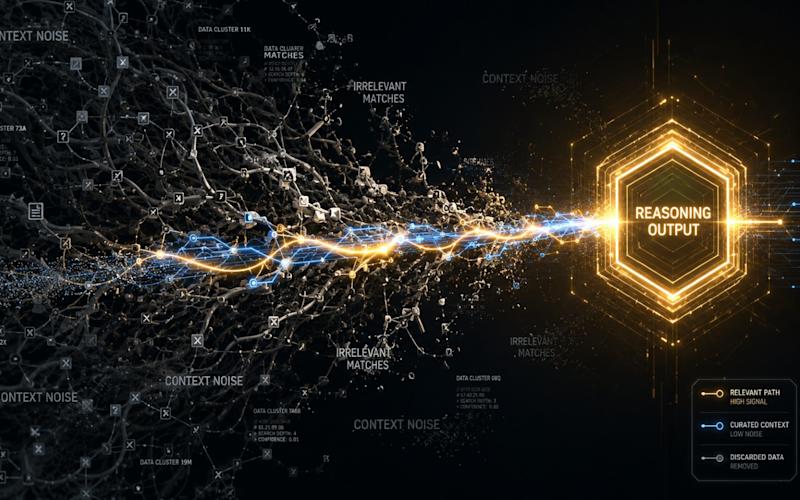
Long-horizon reasoning exposes a core weakness in AI agents: context windows fill up fast, and retrieval pipelines return noise instead of signal.
To solve this, researchers at the National University of Singapore developed MRAgent, a framework that abandons the static “retrieve-then-reason” approach. Instead, it uses a mechanism that allows an agent to dynamically develop its memory based on accumulating evidence.
This multi-step memory reconstruction is integrated into the reasoning process of the large language model (LLM). While not the only framework in this space, MRAgent significantly reduces token consumption and runtime costs compared to other agentic memory management approaches.
The limits of passive retrieval in long-horizon tasks
In classic retrieval pipelines, documents are retrieved through vector search or graph traversal and passed on to an LLM for reasoning. This passive approach fails because it cannot combine reasoning with memory access, creating three major bottlenecks:
These systems cannot revise their retrieval strategy mid-reasoning. If an agent fetches a document and discovers a crucial missing cue — a specific date or person — it has no way to issue a new query based on that finding.
Fixed similarity scores and predefined graph expansions return surface-level matches that flood the LLM’s context window with irrelevant noise, degrading reasoning.
Current systems rely heavily on pre-constructed structures such as top-k results and static relevance functions, limiting the flexibility required to scale across unpredictable, long-horizon user interactions.
The researchers argue that to overcome these limitations, developers must shift toward an “active and associative reconstruction process,” a concept inspired by cognitive neuroscience.
Under this paradigm, memory recall unfolds sequentially rather than operating as a passive read-out of a static database. The system starts with small, specific triggers from the user’s prompt, such as a person’s name, an action, or a place. These initial hints point to connecting concepts or categories instead of massive blocks of text.
By following these metadata stepping stones, the agent gathers small pieces of evidence one by one. It uses each new piece of information to guide its next step until it successfully pieces together the full, accurate story.
How MRAgent implements active memory reconstruction
Instead of viewing memory as a static database, MRAgent (Memory Reasoning Architecture for LLM Agents) treats it as an interactive environment. When processing a complex query, the agent uses the backbone LLM’s reasoning abilities to explore multiple candidate retrieval paths across a structured memory graph.
At each step, the LLM evaluates the intermediate evidence it has gathered and uses it to iteratively optimize its search. It infers new search constraints, pursues the paths with the best information, and prunes irrelevant branches. This allows MRAgent to piece together deeply buried information without filling the LLM’s context with noise.
To make this active exploration computationally efficient and scalable, the framework organizes its database using a “Cue-Tag-Content” mechanism. This operates as a multi-layered associative graph with three node types:
Cues: Fine-grained keywords, such as entities or contextual attributes extracted from user interactions.
Content: The actual stored memory units. These are divided into multi-granular layers, such as episodic memory for concrete events and semantic memory for stable facts and user preferences.
Tags: Semantic bridges that summarize the relational associations between specific Cues and Content.
This structure enables a highly efficient two-stage retrieval process. The LLM first navigates from Cues to candidate Tags. Because Tags explicitly expose the semantic relationships and structural associations of the data, the agent evaluates these short summaries to judge their relevance. The LLM identifies promising traversal paths and discards irrelevant branches before spending compute and prompt tokens to access the detailed, heavy memory contents.
For example, a user might ask an AI agent, “How did Nate use the prize money when he won his third video game tournament?”
MRAgent first extracts fine-grained starting cues from the prompt, such as “Nate,” “video game tournament,” and “win.”
The agent maps these initial cues to the memory graph and looks at the available associative Tags connected to them. The agent sees tags like “Tournament Victory” and “Tournament Participation.” Since it is only concerned with what the person did after they won the championship, MRAgent drops the tournament participation tag and pursues the victory tag.
The agent retrieves the episodic content linked to the chosen Cue-Tag pair, retrieving three distinct memory episodes where Nate won a tournament.
MRAgent looks at the three memories, decides one of them in particular is relevant to the query, and discards the other two.
With this information, it updates its cues and starts another round of discovery and pruning. From the new episodic memory it has retrieved, the agent adds “tournament earnings” to its cues and uses that to traverse new tags and home in on new memories. It repeats this process until it gathers enough information to answer the query, which could be something like “Nate saved the money.”
MRAgent performance on industry benchmarks
MRAgent operates alongside several other frameworks addressing agentic memory building. Alternatives include A-MEM, a graph-based agentic memory framework, and MemoryOS, a hierarchical memory framework. Other persistent memory frameworks include LangMem and Mem0.
The researchers tested MRAgent on the LoCoMo and LongMemEval industry benchmarks. These test the abilities of agents to resolve queries on long-horizon tasks and conversations across dozens of sessions and hundreds of turns of dialogue. The backbone models used were Gemini 2.5 Flash and Claude Sonnet 4.5. The system was tested against standard RAG, A-MEM, MemoryOS, LangMem, and Mem0.
MRAgent consistently outperformed every baseline across both models and all question types by a significant margin.
However, for enterprise developers, the most critical metric is often computational cost. In the LongMemEval tests, MRAgent slashed prompt token consumption to just 118k per sample. By comparison, A-Mem consumed 632k tokens, and LangMem burned through 3.26 million tokens per query. MRAgent also effectively halved the runtime compared to A-Mem, dropping from 1,122 seconds to 586 seconds.
What makes MRAgent efficient in practice is its on-demand behavior. Evaluating tags and pruning irrelevant paths before retrieval saves money and context space. Furthermore, the system autonomously evaluates its accumulated context and inherently knows when to stop searching, completely avoiding redundant data exploration.
Implementation and development catch
While MRAgent is highly effective, the Cue-Tag-Content structure needs to be prepared before the agent can query it. Developers must figure out how to architect the underlying memory database to enable the LLM to efficiently navigate associative items and prune irrelevant paths without exploding compute costs.
Fortunately, developers do not have to manually label or structure this data. The authors designed MRAgent with an automated distillation pipeline that uses LLMs to process raw interaction histories and automatically populate the memory graph. For a developer, the job is to implement and orchestrate this automated ingestion pipeline, rather than manually tag data.
You need to set up a background job or streaming pipeline that passes raw user interactions through prompt templates to extract this metadata before storing it in your graph database.
However, the authors emphasize that this is a lightweight construction phase and MRAgent intentionally keeps ingestion simple.
The authors have released the code on GitHub.
